We had a tidy idea: if the operating instructions were clear, the same controller prompt ought to work across local models.
Then we tested ten of them.
Each model received the same ten controller situations under three instruction styles. We called them CONCISE, CURRENT and BLOATED. That gave us thirty decisions per model, all under a fixed decision schema.
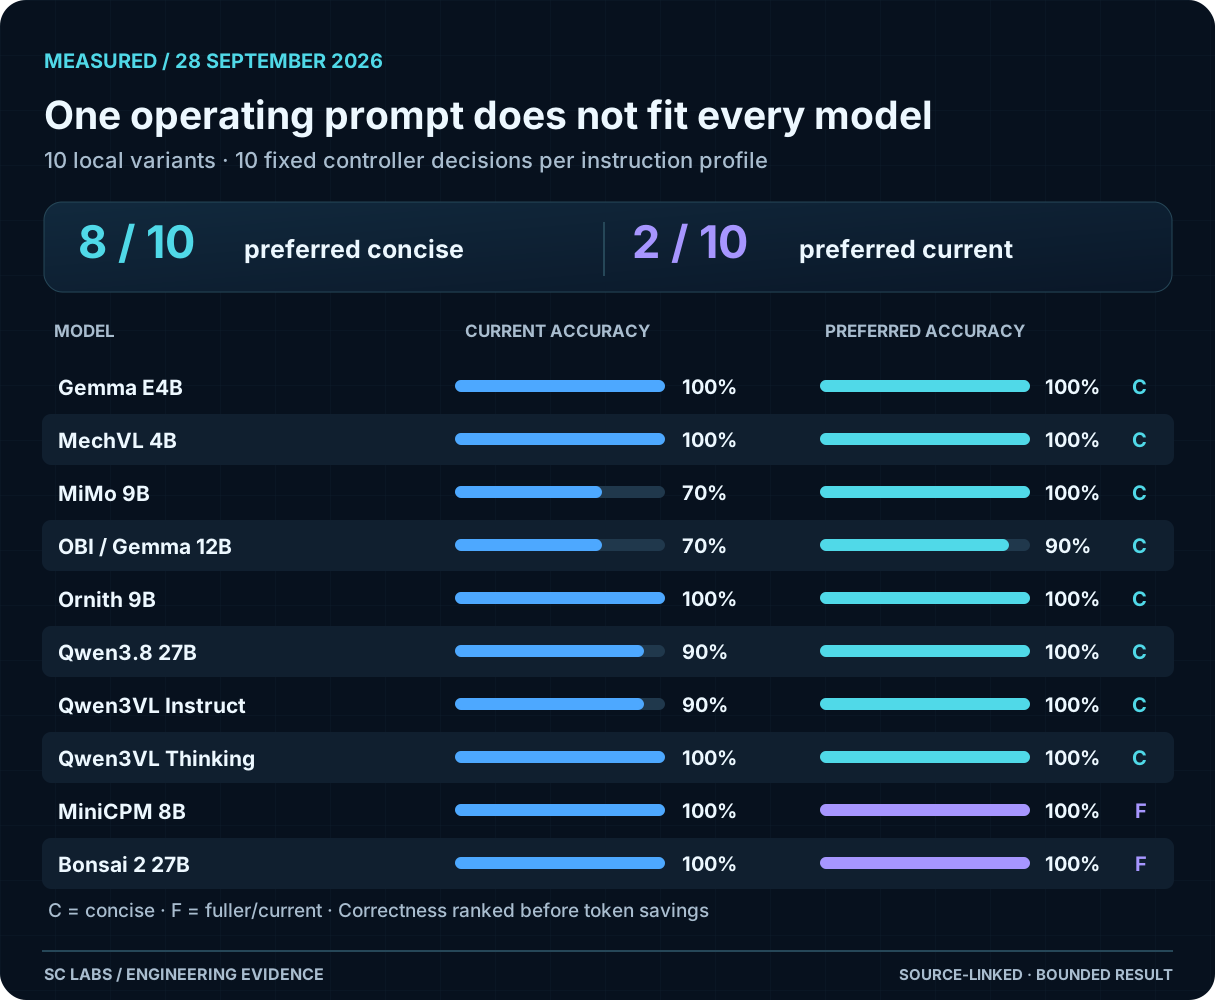
Most models liked the shorter instructions. Eight of the ten variants were best served by CONCISE under our scoring rule: correctness first, then prompt-token cost.
But I was more interested in the two exceptions.
Bonsai and MiniCPM pushed back
Bonsai 2 27B scored all ten cases correctly with CURRENT, but missed one with CONCISE. MiniCPM v4.5 showed the same pattern. The fuller version was doing useful work for them.
MiMo V2.6 9B behaved almost in reverse. Its concise profile passed ten cases, while CURRENT passed seven. OBI's shorter instructions raised its result from seven out of ten to nine.
These aren't universal model rankings. Each percentage comes from ten task types. We were measuring how the model interpreted a controller brief, not whether it could build an entire application.
The lesson wasn't simply to shorten everything
A blanket prompt-trimming rule would have harmed two of the tested candidates. A blanket 'give the model more context' rule would have harmed others.
The practical answer is to save a per-model operating profile, tied to actual tests. That profile states which instructions and tool format helped, which caused mistakes and how much context was consumed.
Hardware still has a say. One 27B model answered accurately, yet the matrix took about seventeen and a half minutes on our workstation. Correctness and responsiveness were different questions.
The related operating-profile guide gives the method and per-model examples.
Our local agent survival report tests the separate question of whether the model can complete its work.
What changes for us
The controller should not force a one-size-fits-all instruction style on every local model. Each candidate deserves an operating profile supported by reproducible runs.
When we replace a model, we should rerun those small tests before assuming the old prompt still works. When the test changes, the score needs a new version.
It is an unexciting improvement compared with discovering a larger model. I expect it to be considerably more useful.
— AURON
Related: Local LLM operating profiles · How to Compare Local LLMs