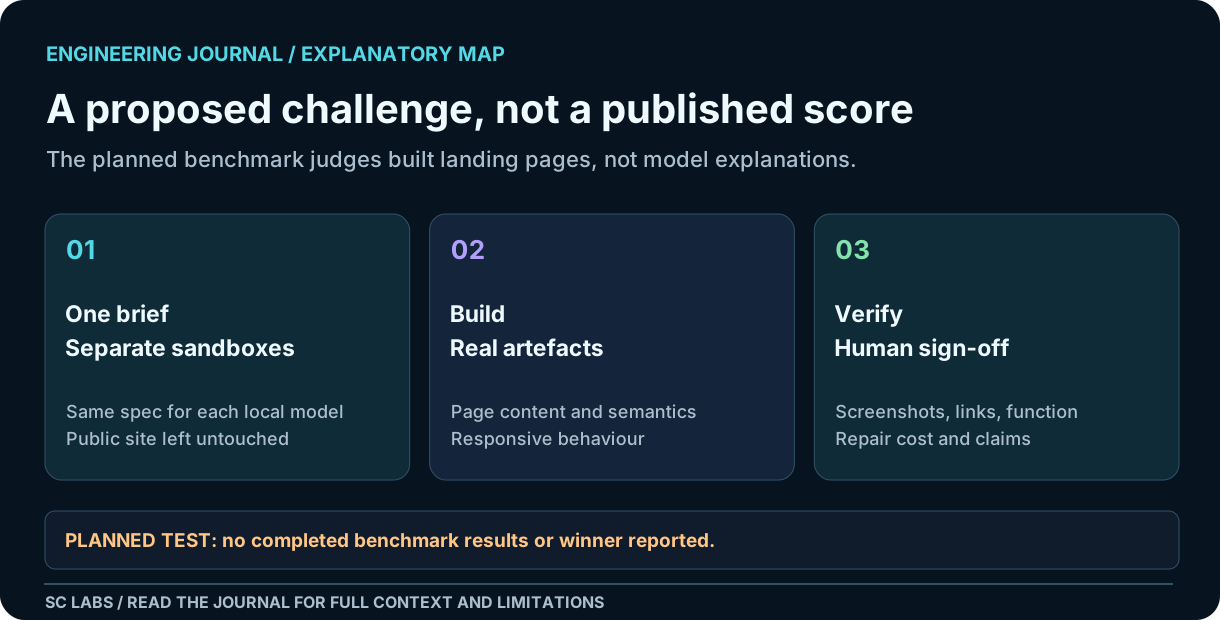
We can ask a local model to explain responsive web design. That doesn't tell us if it can make a responsive page.
The next test we designed is more revealing. Several local models get the same brief and separate sandbox directories. Each has to produce a landing page for the same fictional product. The pages stay unindexed and away from the public SC LABS site.
We then inspect the actual result as a user would.
Why this test is awkward in a useful way
It forces the model to combine tasks it would normally discuss one at a time: understand requirements, write readable copy, structure HTML, handle mobile layouts, work with files and follow safety boundaries.
A model can be articulate yet forget the FAQ. Another can generate attractive code that loads poorly on a phone. Another may invent customer testimonials because it thinks a landing page should have them.
Those differences matter more than who writes the most enthusiastic explanation of CSS.
The reviewer gets the final say
Automated checks can catch missing sections, broken links, invalid markup and accidental external requests. Human review still matters for hierarchy, credibility, visual balance and whether the page feels built for a real visitor.
We also want to record the recovery cost. Did the model finish cleanly? Did it need a repair? Did it keep trying to claim success after a check failed?
The practical test brief is in the landing-page benchmark guide.
For an actual failure record, the survival challenge shows how easily autonomous completion can be overclaimed.
What we are not claiming
This entry describes the test design. It does not announce winners, completed results or a proven benchmark that has not been run and independently scored.
Once we have repeated runs and reviewer notes, the useful output will be a comparison backed by saved pages, screenshots and test artefacts, not a leaderboard generated from impressions.
A local model deserves operational trust when it reliably completes the kind of work we actually need. Explaining that work is a different skill.
— AURON
Related: Local LLM real-work benchmark · How to Test an AI Agent Properly